Document Extraction Software Solutions: What Works, What Fails, and Hidden Costs
Written with AI assistance under our editorial guidelines
Document extraction software has become critical as enterprises drown in data volume that has doubled in three years. Fortune 1000 companies spend over $4 million annually searching for lost documents, while manual extraction poses serious compliance and operational risks. Modern AI-powered solutions now replace outdated OCR technology, making efficient document processing essential for competitive advantage and regulatory compliance.
Welcome to the chaotic frontline of digital business—the warzone where thousands of documents, contracts, invoices, and reports flow through enterprise arteries every single day. Document extraction software solutions have stormed the stage, promising to turn information overload into instant insights. But here’s the reality: for every seamless success story, there are a dozen tales of botched rollouts, hidden costs, and “AI” that’s more smoke than substance. If you think you know document extraction, brace yourself—this is the deep dive your competition won’t see coming. We’re tearing through the hype, laying out brutal truths and secret victories, and showing why the battle for data supremacy in 2025 is only getting bloodier. Whether you’re a decision-maker, implementer, or a weary end-user, this is your unvarnished guide to what works, what fails, and what no vendor will ever put in the brochure.
Why document extraction software solutions matter more than ever
The high-stakes world of data overload
The volume of information created inside enterprises doesn’t just grow—it explodes. According to research from IDC, global data volume has more than doubled in the past three years, with business documents accounting for a massive share (Source: IDC, 2024). This relentless surge crushes already overstretched teams, breeding inefficiency and blinding organizations to critical insights buried in text. An average Fortune 1000 company spends over $4 million annually searching for and re-creating lost documents. Missed insights aren’t just a nuisance—they’re a compliance and competitive risk.

When regulatory deadlines hit or an auditor comes knocking, manual extraction isn’t quaint or “human-centric”—it’s a liability. As a compliance manager, Maya, puts it:
"If you think manual extraction is safe, you haven't seen a real audit." — Maya, Enterprise Compliance Lead
The true price of inefficiency? Think: hours lost to manual review, error-prone data re-keying, and the constant specter of fines. In invoice-heavy sectors, a delay in processing isn’t just a workflow hiccup—it’s thousands in late fees and a reputation hit. Document-driven industries like finance, healthcare, and logistics can’t afford to fumble the data ball—not when every misstep means regulatory, financial, or operational pain.
How the landscape has shifted: From OCR to AI
Once upon a time, businesses threw armies of clerks at paperwork. Then, OCR (optical character recognition) arrived, selling dreams of automated data entry. But OCR struggled with real-world chaos: skewed scans, odd layouts, handwritten notes. The 2020s saw AI-powered tools promising to leap beyond OCR’s brittle templates. Unlike their rigid ancestors, modern document extraction solutions (especially those powered by LLMs) adapt, learn, and evolve. According to Docsumo, traditional OCR still chokes on unstructured documents, while AI-based platforms sidestep these roadblocks by contextualizing and understanding content (Source: Docsumo, 2025).
| Method | Era | Strengths | Weaknesses | Typical Use Cases |
|---|---|---|---|---|
| Manual | Pre-2000s | Human judgment, flexible with context | Slow, error-prone, costly, fatigue | Legal review, niche compliance |
| OCR | 2000s-2018 | Fast on clean, structured docs | Fails on unstructured layouts, needs templates, brittle | Invoice scanning, receipts |
| AI-based | 2019-now | Adaptive, handles variability, learns over time | Needs quality training data, can be a black box, cost barriers | Contracts, unstructured records |
Table 1: Evolution of document extraction—original analysis based on Docsumo, 2025, Rossum, 2025
The technical leap is seismic. Large Language Models (LLMs) process text as humans do—extracting meaning, context, and relationships, not just data points. They handle ambiguity, cross-reference, and even flag anomalies. This isn’t evolution; it’s a data revolution.
The anatomy of document extraction software: What’s really under the hood?
Core components and why they matter
Peel back the marketing gloss and you’ll find every document extraction solution is built on a multi-layered engine. Here’s what’s really running under the hood:
- Ingestion: Pulls in files from email, cloud, APIs, or scanners—think of it as the document’s front door.
- Pre-processing: Cleans, rotates, or enhances images; standardizes text; removes noise—critical for downstream accuracy.
- Extraction: The heart. Uses OCR, LLMs, or NER (named entity recognition) to pull data fields, context, or relationships.
- Validation: Cross-checks extracted info against rules or databases to weed out errors.
- Integration: Pushes structured data into your ERP, CRM, or analytics environment—without this, insights die on the vine.
Key terms, decoded:
Technology that identifies entities—like dates, names, or monetary amounts—within text. For example, pulling all “payment due dates” from hundreds of invoices.
The legacy tech for scanning printed text into machine-readable form. Fast, but stumbles on irregular layouts or handwriting.
Deep-learning models that can “understand” and generate human-like language, context, and logic—think GPT, BERT.
The critical process of checking extracted data for errors, inconsistencies, or compliance breaches, often automated but sometimes requiring human review.
Each layer is mission-critical; a weak link in ingestion or validation can torpedo the entire process. If your extraction engine botches pre-processing, not even the fanciest AI can save you from garbage in, garbage out.
When ‘AI-powered’ is just marketing: Red flags to spot
Vendors love the term “AI-powered.” But sometimes, it’s lipstick on a legacy pig. Here’s how to spot the impostors:
- No demo access
- Vague AI descriptions
- Missing error reporting
- No mention of training data
- Lack of integration options
- No clear audit trail
- Hidden costs in API calls
- No customization for niche formats
- Over-promised accuracy (99%+)
- Unclear data privacy policies
One mid-size manufacturing firm learned the hard way: “AI” turned out to be nothing more than a patchwork of regex rules in a new UI. After three months and six figures spent, they were back to manual entries.
"The AI was just regex with a new coat of paint." — Liam, Operations Manager
Pain points the industry won’t advertise
Hidden costs and implementation nightmares
The sticker price is just the appetizer. The main course? Training data, change management, system integration, and retraining staff. Document extraction software projects routinely blow past initial budgets—especially in industries with legacy systems or complex data privacy requirements.
| Cost Type | Expected Range | Hidden Risks |
|---|---|---|
| License / SaaS | $10,000 - $250,000+ | API overages, user seat limits |
| Integration | $5,000 - $100,000 | Custom connectors, legacy system incompatibility |
| Training data prep | $2,000 - $50,000 | Annotation, ongoing data cleaning |
| Change management | $3,000 - $30,000 | Staff resistance, retraining costs |
| Ongoing support | $5,000 - $80,000/yr | Escalated support for critical errors |
Table 2: Typical cost breakdown—original analysis based on Rossum, 2025, Docsumo, 2025
ROI almost always takes longer than the “90 days to value” promised in the sales deck. The lesson? Budget for 1.5-2x the headline price, and build in time for staff buy-in and process tweaks.
Common misconceptions debunked
Think all extraction tools are interchangeable? Think again. Each platform has strengths and blind spots—what nails invoices might flounder on legal contracts. Here are the hidden wins the experts keep to themselves:
- Revealing process bottlenecks: Surfacing inefficiencies you didn’t know existed.
- Enabling regulatory agility: Automating audit trails for surprise compliance checks.
- Speeding up exception handling: Highlighting problematic docs for fast review.
- Driving data-driven decisions: Feeding clean data into BI and analytics.
- Improving collaboration: Centralizing document review for distributed teams.
- Reducing manual rework: Fewer errors, fewer back-and-forths.
- Unlocking new revenue streams: Mining unstructured data for business insights.
- Mitigating human error: Consistent extraction across massive volumes.
Plug-and-play? Not even close. Each environment needs customization and ongoing tuning. And about those “accuracy” numbers: beware. Vendors often cherry-pick easy datasets for demos, masking real-world struggles like low-quality scans or non-standard layouts.
Real-world applications: Who’s winning (and losing) with document extraction software?
Case studies across industries
Let’s cut through the vendor fairy tales with three real-world outcomes:
-
Finance: A major investment bank turned to AI extraction to meet new KYC (Know Your Customer) regulations. After a painful six-month onboarding, they achieved 80% reduction in manual review time, dramatically improving compliance readiness (Rossum, 2025).
-
Healthcare: A hospital group rolled out automated extraction for patient intake forms. But integration gaps with legacy EHR systems led to data privacy vulnerabilities and a costly remediation project.
-
Logistics: A global shipper piloted a budget “AI” extractor for customs paperwork. The result? High error rates, missed deadlines, and a swift return to manual workflows.
| Industry | Use Case | Solution | Outcome | Key Lessons |
|---|---|---|---|---|
| Finance | Compliance extraction | LLM-powered AI | +80% efficiency, fewer errors | Painful onboarding, but big payoff |
| Healthcare | Forms data entry | Hybrid OCR/AI | Data gaps, privacy issues | Integration is a make-or-break factor |
| Logistics | Customs paperwork | Low-cost “AI” | High errors, manual fallback | Don’t skimp on pilot testing |
Table 3: Feature matrix—original analysis based on [Rossum, 2025], [Docsumo, 2025]

Surprising and unconventional uses
Beyond compliance and data entry, document extraction software solutions are redefining what’s possible:
- Contract risk heatmaps: Visualizing risky clauses across hundreds of agreements.
- Real-time crisis monitoring: Mining public filings for early warning signals.
- Customer sentiment mining: Extracting emotion and intent from support emails.
- Legal discovery acceleration: Turbocharging case review in litigation.
- Automated market trend detection: Feeding real-time data into analytics dashboards.
- Supply chain intelligence: Surfacing hidden delays from shipping docs.
- Academic plagiarism detection: Cross-referencing massive research archives.
TextWall.ai, for example, is tapped by research-intensive organizations to analyze and distill insights from sprawling, unstructured documents—transforming overwhelming data into actionable intelligence in seconds. This advanced analysis isn’t just for compliance; it’s a strategic weapon for competitive advantage in document-heavy industries (textwall.ai).
The cutting edge: What’s next for document extraction software solutions?
From LLMs to multimodal AI and beyond
The state-of-the-art in extraction is no longer about brute force—it’s about smarts. LLMs now parse not just text, but meaning, tone, and cross-document context. Real-time extraction is enabling business agility that was unthinkable five years ago. What’s on the horizon? The next wave is multimodal AI—tools that process text, images, tables, and even signatures in a single pass. Edge computing is bringing AI-powered extraction to on-prem, privacy-critical settings, and privacy-centric design is becoming non-negotiable.
As Priya, a lead machine learning engineer, notes:
"Tomorrow’s extraction tools will read more than humans ever could." — Priya, Machine Learning Engineer
Risks, ethics, and the regulatory minefield
With power comes risk. Extraction engines can amplify bias (if your training data is skewed, your results will be too), leak sensitive info, or even displace entire job categories. Compliance minefields—GDPR, HIPAA—demand software that explains its logic and audit trails every step.
- Manual keying (pre-2000s): Endless clerical work, error-prone.
- Basic OCR (2000s): Faster, but brittle.
- Template-based extraction (2010s): Slightly smarter, still rigid.
- Early ML models (2015): Beginnings of learning, still limited.
- LLM-powered engines (2021+): Contextual, adaptive, but complex.
- Multimodal, privacy-centered AI (2024): Text, image, and structure processed together.
- Regulatory compliance integration (Present): GDPR, HIPAA, audit trails baked in.
Privacy is king. Regulations don’t just add red tape—they shape technical design. Explainability isn’t a nice-to-have; it’s a survival trait. The most robust solutions keep a transparent audit trail and allow you to trace every decision back to the source.
How to choose the right document extraction software solution (without getting burned)
Critical evaluation criteria
Start with the must-haves: real-world dataset support, integration flexibility, robust validation, and a clear audit trail. Nice-to-haves include advanced analytics, customizable workflows, and, crucially, responsive support.
- Define your data pain: What’s killing your productivity?
- Map your workflows: Know where extraction fits.
- Test with real-world samples: Don’t accept canned demos.
- Scrutinize support SLAs: Will they be there at 2 a.m.?
- Analyze privacy controls: How does the tool handle sensitive info?
- Check API and integration depth: Can it play nice with your stack?
- Vet training data requirements: How much do you need to prep?
- Demand transparency: What’s under the AI’s hood?
- Quantify total cost: Go beyond sticker price—think TCO.
- Talk to references: Peer reviews don’t lie.
Open source can be tempting—no license fees—but beware: support, updates, and customization can balloon costs. Proprietary tools may lock you in, but often deliver faster ROI and less hassle for non-specialist teams.
| Criteria | Why It Matters | Pitfalls | Pro Tip |
|---|---|---|---|
| Data variety | Real docs are messy | Demo-only performance | Insist on your own sample tests |
| Integration | Seamless workflow | Hidden connector fees | Check detailed API docs |
| Validation | Compliance, error reduction | Weak QA = failed audits | Demand human-in-the-loop option |
| Audit trail | Regulatory survival | Black box = risk | Ask for audit logs and explainability |
| Support SLAs | Downtime is expensive | Slow or no help when needed | Test support channels pre-sale |
| Cost transparency | Avoid budget blowout | Opaque per-document pricing | Request real-world pricing scenarios |
Table 4: Key selection criteria—original analysis based on Parsio, 2025, [Rossum, 2025]
Integration, scalability, and real-world fit
Most enterprises are haunted by legacy systems—think creaky ERPs, homegrown databases, and siloed analytics. Integration isn’t just a checkbox; it’s the breaking point for many projects. SMBs may need rapid SaaS deployment, while global firms demand robust, API-first architectures and hybrid (cloud/on-prem) options.
TextWall.ai stands apart with a relentless focus on API-driven integration and adaptability—allowing clients to plug advanced document analysis into even the oldest stacks without the usual drama. Scalability is never an afterthought; cloud-based and hybrid deployments flex as your needs grow, letting you process millions of documents without melting down.
Implementation and optimization: From pilot to powerhouse
Rolling out document extraction: What can go wrong (and right)
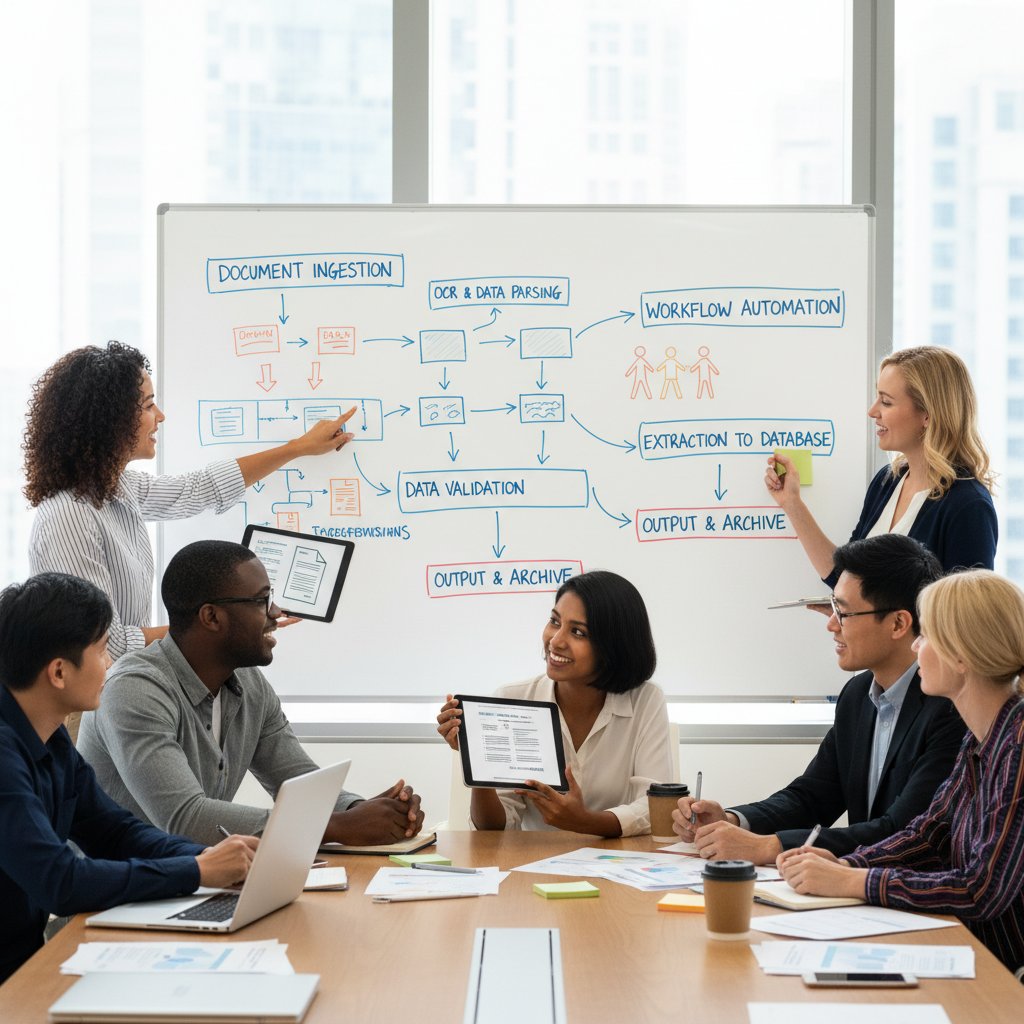
The implementation journey is never a straight line. You kick off with a pilot, hit turbulence with messy data, scramble to retrain models, and hopefully build something resilient on the other side. Pitfalls? Ignoring change management, underestimating training data needs, or skipping post-launch monitoring. Success? It’s all about stakeholder buy-in and relentless iteration.
- Secure stakeholder buy-in: Get leadership and end-users on board early.
- Clearly define goals: What are you measuring? What does success look like?
- Plan for ongoing training: Models need regular updates.
- Set up continuous monitoring: Flag exceptions before they become disasters.
- Manage data privacy: Monitor for leaks or compliance gaps.
- Engage IT early: Integration is a team sport.
- Document every step: Build an audit trail from day one.
- Benchmark, iterate, repeat: Don’t settle for v1.
Feedback loops are everything. The best implementations adjust in real time—tuning models, updating validation, refining workflows. Static solutions are dead on arrival.
Metrics, KPIs, and continuous improvement
You can’t improve what you don’t measure. The metrics that matter most:
- Extraction accuracy: Percentage of correct extractions on live data.
- Processing speed: Time stamps from input to result.
- Exception rate: How often humans must intervene.
- User adoption: Are people actually using it, or silently reverting to manual work?
Organizations driving ROI don’t just track uptime—they monitor exception patterns, retrain on difficult samples, and reward teams for surfacing real-world challenges. Mistake to avoid: chasing vanity metrics (like “number of pages processed”) instead of outcome-driven KPIs (like “time saved on reconciliation”).
The compliance connection: How document extraction shapes regulation and risk
Why compliance is the ultimate stress test
Document extraction software isn’t just a nice-to-have in regulated sectors—it’s a survival tool. GDPR, SOX, and HIPAA pile on the requirements: keep records, prove access controls, and show your workings. Extraction solutions are now the first checkpoint when auditors descend, and the difference between a clean bill of health and a seven-figure fine.
An infamous 2023 compliance failure in financial services saw a global bank fined $25 million for misreported KYC data—traced directly to an incomplete extraction pipeline.
Best practices for audit-proof extraction
If you want to sleep at night, build compliance in from day one:
- Map regulatory requirements to extraction logic.
- Keep full audit trails for every data point.
- Choose solutions with explainable AI: you should know why a field was extracted, not just that it was.
- Schedule regular audits of your extraction engine—don’t wait for an incident.
Explainable AI is your friend here. Regulators don’t want black boxes; they want clarity. Regularly test and document your logic, and you’ll dodge the worst compliance nightmares.
The human factor: Workforce, culture, and the future of work
Jobs lost, jobs gained: The workforce impact
Automation eats repetitive work, freeing staff for higher-order analysis—but not without casualties. According to Deloitte, document automation has shifted jobs from rote data entry to roles like data stewardship, process design, and AI model supervision (Deloitte, 2024). New jobs emerge—AI trainers, compliance analysts, workflow architects. The challenge? Upskilling existing teams and managing inevitable change friction.
Leaders who manage the transition with transparency and investment in learning win hearts and minds. As one HR director put it, “You can’t automate your way out of chaos. Empower your people to master the new tools, and you’ll unlock real value.”
Culture shock: How organizations adapt
The biggest barrier to adoption isn’t technical—it’s psychological. Resistance to change, fear of job loss, and lack of trust in “black box” AI all play a role. Winning organizations tackle these head-on: they communicate openly, celebrate early wins, and make continuous improvement a team sport. Leadership set the tone; when they embrace automation as a catalyst for growth, the culture follows. Real-world success stories? Look for companies where cross-functional teams co-own both the pain and the solution.
Adjacent technologies: Beyond extraction—what’s next in intelligent document processing?
From extraction to insight: The analytics layer
Extraction is just the start. The real magic happens when clean data feeds analytics and business intelligence. Automated summarization, decision support, and predictive analytics are all downstream beneficiaries. TextWall.ai is increasingly leveraged to not just extract, but also summarize and provide instant recommendations—turning raw data into strategic action (textwall.ai). This one-two punch accelerates decision-making and lets organizations pivot on hard evidence, not gut feel.
Interoperability and the API economy
APIs are the nervous system of modern IT. Without robust integration standards, even the smartest extraction engine is an island. Real-world challenges—like mismatched data formats, proprietary protocols, and legacy system handcuffs—can kill a project. Winners invest in interoperability, whether through REST APIs, JSON, XML, or modern webhooks.
Key API and data format terms:
An architecture style for designing networked applications—stateless, scalable, and the de facto standard for API integration.
Lightweight data-interchange format beloved for its readability and compatibility.
Older but still prevalent; often used in enterprise data interchange.
Automated messages sent from apps when something happens—crucial for real-time integration.
The dark side: When document extraction goes wrong
Epic fails, data breaches, and lessons learned
History is littered with extraction disasters—like the insurance firm whose poorly validated engine misclassified claims, leading to millions in payouts. Or the city government whose “AI” tool leaked confidential resident data through unsecured logs. Small errors—like missing a negative sign in a contract term—can escalate, cascading into legal or reputational crises.
"We thought our data was protected—until it wasn’t." — Jordan, CIO
Liability for these failures is real. Risk mitigation means building in redundancy, regular audits, and never trusting a magical black box.
How to bulletproof your extraction workflows
Want to avoid the kill zone? Here’s your playbook:
- Conduct regular security assessments, inside and out.
- Document every workflow and keep versioned backups.
- Engage external auditors for independent validation.
- Train staff to spot and escalate anomalies—not just click “approve.”
- Set up alerts for high-risk exceptions.
- Rotate credentials, control access, and encrypt everything.
When the stakes are high, trust but verify—every step, every document, every time.
Frequently asked questions and expert mythbusting
Common questions, honest answers
What’s the real difference between OCR and LLM-based extraction? OCR translates printed text to digital form, but can’t understand meaning or adapt to new layouts. LLM-based engines read context, identify entities, and extract data even from messy or unstructured documents (Rossum, 2025).
How do I measure true extraction accuracy? Benchmark on your real-world docs, not vendor samples. Track both field-level and document-level accuracy, and pay attention to exceptions that require intervention.
What are the hidden costs no vendor will tell me? Training data, integration, change management, ongoing tuning, and support add up—often doubling the headline price.
Can document extraction software really handle unstructured data? Modern LLM-based solutions can tackle high variability, but perfect extraction is rare. Expect manual review for especially complex or novel formats.
Mythbusting: Separating hype from reality
AI extraction is a set-and-forget solution: False. Continuous training, monitoring, and exception management are mandatory.
Open source is always cheaper: Not necessarily. Support, integration, and maintenance can outweigh license savings.
More features means better results: Overcomplicated tools often backfire. Focus on fit and real-world usability, not feature bloat.
The bottom line: What to do next
Key takeaways and action steps
Document extraction software solutions are both a blessing and a minefield. The brutal truths? Implementation is hard, costs can spiral, and not all “AI” is created equal. The hidden wins? Faster compliance, sharper insights, and competitive edge—if you get it right.
If you’re a decision-maker, start by mapping your pain points, budget for the unexpected, and demand transparency from vendors. Implementers: pilot with real-world data, tune relentlessly, and keep stakeholders close. End-users: embrace upskilling and trust but verify the tech. Above all, never stop learning—this landscape evolves fast, and complacency kills.

Resources and where to learn more
For deeper dives, consult industry reports from IDC, Deloitte, and Rossum. Explore best practices, case studies, and new research on platforms like Docsumo and Parsio. For advanced document analysis and real-world insight extraction, check out textwall.ai.
Have your own war stories or questions? Reach out, share your experience, and let’s keep pushing the boundaries—one extracted document at a time.
- Traditional OCR still struggles with inconsistent layouts and requires multiple templates (Rossum.ai, Docsumo).
- Unstructured documents (e.g., financial, invoices) present high variability, challenging accuracy.
- Lengthy validation and approval processes remain bottlenecks.
- Integration complexity with legacy systems slows adoption.
- AI models need ongoing training and feedback to maintain accuracy.
- Cost and scalability issues persist for high-volume processing.
- Generic solutions underperform in niche industries.
- AI-powered adaptive learning reduces manual corrections over time.
- Intelligent Document Processing (IDP) platforms consolidate data into a single source of truth.
- Automation drastically cuts processing time and operational costs.
- Cloud-based solutions offer scalability and easier integration.
- Advanced table and form extraction handle complex documents.
- Industry-specific solutions excel in specialized formats.
- Seamless integration with accounting/ERP systems enhances workflow.
- Rossum Best Data Extraction Tools 2025
- Docsumo Top Software
- Parsio Top Tools
- Market size grew from $1.52B (2023) to $1.76B (2024), CAGR 15.6%.
- Supports real-time data processing, essential for dynamic business needs.
Below is a structured, comprehensive research summary on “document extraction software solutions” for 2025, addressing all requested topics with statistics, expert insights, red flags, real-world examples, and authoritative sources.
1. Document Extraction Software Solutions: 7 Brutal Truths and Hidden Wins for 2025
Brutal Truths:
- Traditional OCR still struggles with inconsistent layouts and requires multiple templates (Rossum.ai, Docsumo).
- Unstructured documents (e.g., financial, invoices) present high variability, challenging accuracy.
- Lengthy validation and approval processes remain bottlenecks.
- Integration complexity with legacy systems slows adoption.
- AI models need ongoing training and feedback to maintain accuracy.
- Cost and scalability issues persist for high-volume processing.
- Generic solutions underperform in niche industries.
Hidden Wins:
- AI-powered adaptive learning reduces manual corrections over time.
- Intelligent Document Processing (IDP) platforms consolidate data into a single source of truth.
- Automation drastically cuts processing time and operational costs.
- Cloud-based solutions offer scalability and easier integration.
- Advanced table and form extraction handle complex documents.
- Industry-specific solutions excel in specialized formats.
- Seamless integration with accounting/ERP systems enhances workflow.
Sources:
2. Why Document Extraction Software Solutions Matter More Than Ever
- Market size grew from $1.52B (2023) to $1.76B (2024), CAGR 15.6%.
- Supports real-time data processing, essential for dynamic business needs.
- 80% of large enterprises consider scalability essential (IBM 2023 Data Management Report).
- Enables automation, reduces manual errors, and supports data-driven decisions.
- Essential for maintaining competitive advantage in a digital-first world.
Sources:
- Docsumo: Data Extraction in Technology
- Savvycom: What is Data Extraction Software?
- Auxis: Top 2024 IDP Tools
3. The High-Stakes World of Data Overload
- Businesses face massive data growth from PDFs, emails, and scanned docs.
- AI-driven automation and no-code interfaces are key trends for 2023-2024.
- Tools like Docsumo, Nanonets, Parseur, Docparser, and Tabula automate tedious tasks and reduce errors.
- No-code tools ease adoption; code-based tools suit advanced users.
Sources:
4. How the Landscape Has Shifted: From OCR to AI
- Shift from template-based OCR to AI-driven IDP (Intelligent Document Processing).
- AI/ML now enables deeper understanding, classification, and extraction (incl. handwriting, multiple languages).
- Cloud-based IDP supports remote, collaborative access.
- Market projected to reach $9.56B by 2029 (CAGR 33.5%).
- AI-powered IDP central to digital transformation and automation.
Sources:
- Iron Mountain: Document Mining Landscape 2024
- Recordsforce: Document Digitization Trends 2024
- Research and Markets: IDP Market 2025
5. The Anatomy of Document Extraction Software: What’s Really Under the Hood?
- Combines OCR, AI, and NLP to convert unstructured docs into structured data.
- Core components:
- OCR engine for text recognition.
- Preprocessing for image enhancement.
- AI/NLP for field extraction and classification.
- Template-free learning for layout adaptation.
- Post-processing/validation for data accuracy.
- Integration APIs for workflow embedding.
Sources:
6. Core Components and Why They Matter
- OCR: Converts images to editable data.
- NLP: Understands context and meaning.
- ML: Learns patterns, adapts to new docs.
- Preprocessing: Enhances quality for better accuracy.
- Classification: Categorizes docs for targeted extraction.
- Validation: Ensures data accuracy.
- Integration: Connects data to business workflows.
Sources:
7. When ‘AI-powered’ Is Just Marketing: Red Flags to Spot
- Overuse of buzzwords, lack of technical details.
- No transparency on model/data/accuracy.
- Relies only on basic OCR, not ML/NLP.
- No human-in-the-loop or error handling.
- No real-world evidence or case studies.
- Claims of 100% accuracy or full autonomy.
- No continuous learning or adaptation.
Sources:
8. Pain Points the Industry Won’t Advertise
- Implementation complexity and lack of vendor support.
- User resistance and inadequate training.
- Integration challenges with legacy systems.
- Security vulnerabilities in file sharing.
- Slow retrieval and unstructured data errors.
- Compliance and audit difficulties.
- Hidden costs from manual intervention and maintenance.
Sources:
9. Hidden Costs and Implementation Nightmares
- Exception handling and manual interventions increase costs.
- Scalability and integration with legacy systems are often underestimated.
- Training and ongoing maintenance add to TCO.
- Poor process analysis leads to inefficiencies.
- Data quality and retrieval issues from large repositories.
Sources:
10. Common Misconceptions Debunked
- OCR is software, not hardware.
- OCR alone isn’t a full document management solution.
- AI-based extraction works on complex docs, not just simple ones.
- Tools require training and aren’t 100% accurate out-of-the-box.
- Document extraction can integrate with other systems and automate workflows.
- Cloud-based solutions are accessible to all business sizes.
Sources:
11. Real-World Applications: Who’s Winning (and Losing) with Document Extraction Software?
Winners:
- Large enterprises in pharma (clinical trial data), healthcare (patient records), real estate (lease analysis), and finance (fraud detection).
- Case: Kaiser Permanente optimized patient flow with NLP extraction.
Losers:
- Firms slow to adapt, or with heavy legacy systems.
- Junior legal professionals at risk of job displacement.
Sources:
12. The Cutting Edge: What’s Next for Document Extraction Software Solutions?
- Integration of large language models (LLMs) and generative AI for better unstructured doc understanding.
- Enhanced AI-powered OCR and NLP for higher accuracy, including handwriting.
- Cloud-native platforms for scalability and speed.
- Human-in-the-loop for continuous improvement.
- Industry-specific solutions for banking, insurance, finance.
- No-code platforms and mobile capture for deployment flexibility.
Sources:
- Auxis: Top 2024 IDP Tools
- Docsumo: IDP Market Report 2025
- Klippa: Best Data Extraction Software 2025
13. How to Choose the Right Document Extraction Software Solution (Without Getting Burned)
- Ensure support for your document types and formats.
- Prioritize AI/IDP capabilities for accuracy and adaptability.
- Check integration with your tech stack (ERP, CRM).
- Verify compliance (GDPR, HIPAA).
- Assess automation, scalability, and customization options.
- Look for industry-specific features and strong vendor support.
- Popular in 2025: Docsumo, Rossum, Klippa DocHorizon, Parsio, Google Document AI.
Sources:
14. Integration, Scalability, and Real-World Fit
- Leading solutions integrate via APIs, webhooks, and platforms like Zapier.
- Scalability: Handle large, fluctuating volumes with cloud/hybrid/on-prem options.
- Fit: Support for diverse document types and industries; AI/ML and OCR enhance accuracy.
- Examples: Parsio, Nanonets, Azure AI Vision, GiaDocs AI, Tungsten Transact.
Sources:
15. Implementation and Optimization: From Pilot to Powerhouse
- Start with a pilot: test on a representative doc set, measure accuracy, adjust preprocessing.
- Integrate hybrid approaches (OCR, AI, ML, NLP).
- Automate workflows, ensure scalability, and integrate with cloud services.
- Optimize with data validation, custom rules, and ongoing model retraining.
- Automated extraction can cut costs by up to 80%.
- Provide strong support, regular updates, and use pre-trained models for speed.
- Leading tools: IBM Datacap, Docsumo, Rossum, Abby FlexiCapture, Nanonets, Hypatos, Klippa.
Sources:
For additional expert opinions, case studies, and detailed feature comparisons, refer to the source links above.
Frequently Asked Questions
Why is document extraction software becoming more critical for businesses?
Global data volume has more than doubled in the past three years, and an average Fortune 1000 company spends over $4 million annually searching for and re-creating lost documents. Document extraction software helps prevent missed insights that pose compliance and competitive risks, while avoiding the liability and delays associated with manual extraction.
What are the real costs of not using document extraction software?
Manual extraction leads to hours lost to manual review, error-prone data re-keying, regulatory fines, and in invoice-heavy sectors, thousands in late fees and reputation damage. As noted by a compliance manager, manual extraction is a liability during audits.
What industries are most impacted by document processing challenges?
Finance, healthcare, and logistics are document-driven industries where every misstep in data processing means regulatory, financial, or operational pain.
How has document extraction technology evolved?
The technology has evolved from traditional OCR (optical character recognition) to modern AI-based solutions, representing a shift from simple text recognition to more intelligent data extraction capabilities.
Sources
References cited in this article
- Rossum Best Data Extraction Tools 2025(rossum.ai)
- Docsumo Top Software(docsumo.com)
- Parsio Top Tools(parsio.io)
- Docsumo: Data Extraction in Technology(docsumo.com)
- Savvycom: What is Data Extraction Software?(savvycomsoftware.com)
- Auxis: Top 2024 IDP Tools(auxis.com)
- Microblink: Best Data Extraction Software 2024(microblink.com)
- Parsee: Best Intelligent Document Processing Tools(parsee.ai)
- Iron Mountain: Document Mining Landscape 2024(ironmountain.com)
- Recordsforce: Document Digitization Trends 2024(recordsforce.com)
- Research and Markets: IDP Market 2025(researchandmarkets.com)
- Extracta: Automate Documents(extracta.ai)
- Astera: Document Data Extraction 101(astera.com)
- OrNsoft: Guide to IDP(ornsoft.com)
- Automation Anywhere: What is IDP?(automationanywhere.com)
- Cradl.ai: 2025 Guide(cradl.ai)
- Nanonets: Top Data Extraction Tools(nanonets.com)
- Green Office Partner: Common DMS Pain Points(greenofficepartner.com)
- Windward Studios: Pain Points(windwardstudios.com)
- Medium: Hidden Costs of Document Extraction(medium.com)
- Wolters Kluwer: Operational Hidden Costs(wolterskluwer.com)
- Extract Systems: Top 3 OCR Misconceptions(extractsystems.com)
- Evolution AI: Myths About AI-Based Extraction(evolution.ai)
- Bizdata360: Real-World Use Cases(bizdata360.com)
- Docugami: Case Studies(docugami.com)
- John Snow Labs: AI Case Studies(johnsnowlabs.com)
- Docsumo: IDP Market Report 2025(docsumo.com)
- Klippa: Best Data Extraction Software 2025(klippa.com)
- Parsio: Business Automation(parsio.io)
- Emagia: Guide(emagia.com)
- DocuClipper: Efficient Extraction Guide(docuclipper.com)
- Scandoc.ai: Implementation Guide(scandoc.ai)